Nov 5, 2026
12 min
How to Schedule and Monitor Web Scrapers (2026 Guide)
Run your scraper on autopilot with cron, systemd, GitHub Actions, n8n or Apify, then catch silent failures with heartbeats and success-rate checks.
Read Article
Tips, tools, and best practices for web scraping, data extraction, and automation.
81 articles
Run your scraper on autopilot with cron, systemd, GitHub Actions, n8n or Apify, then catch silent failures with heartbeats and success-rate checks.
Raw scraped data is always messy. Here’s a tested five-step pipeline to normalize, validate, deduplicate and store it, plus how to choose between CSV, SQLite, PostgreSQL and Parquet.
Build a Node.js scraper with Axios and Cheerio, add an authenticated proxy, rotate a proxy pool with retries, and scrape JavaScript-heavy pages with Playwright.
CSS selectors or XPath? See when each one wins for web scraping, with tested side-by-side examples, the truth about speed, and selector patterns that survive site redesigns.
Build your first BeautifulSoup scraper step by step: fetch pages with Requests, pick a parser, extract fields with CSS selectors, follow pagination politely and save the results to CSV.
Add proxies to a Scrapy spider the right way: a single proxy, authentication, a rotating middleware that switches IPs on retries, and the settings that keep large crawls polite.
How to handle a web scraping rate limit: read 429s and Retry-After, back off with jitter, cap concurrency per host, and tune Scrapy AutoThrottle to crawl politely.
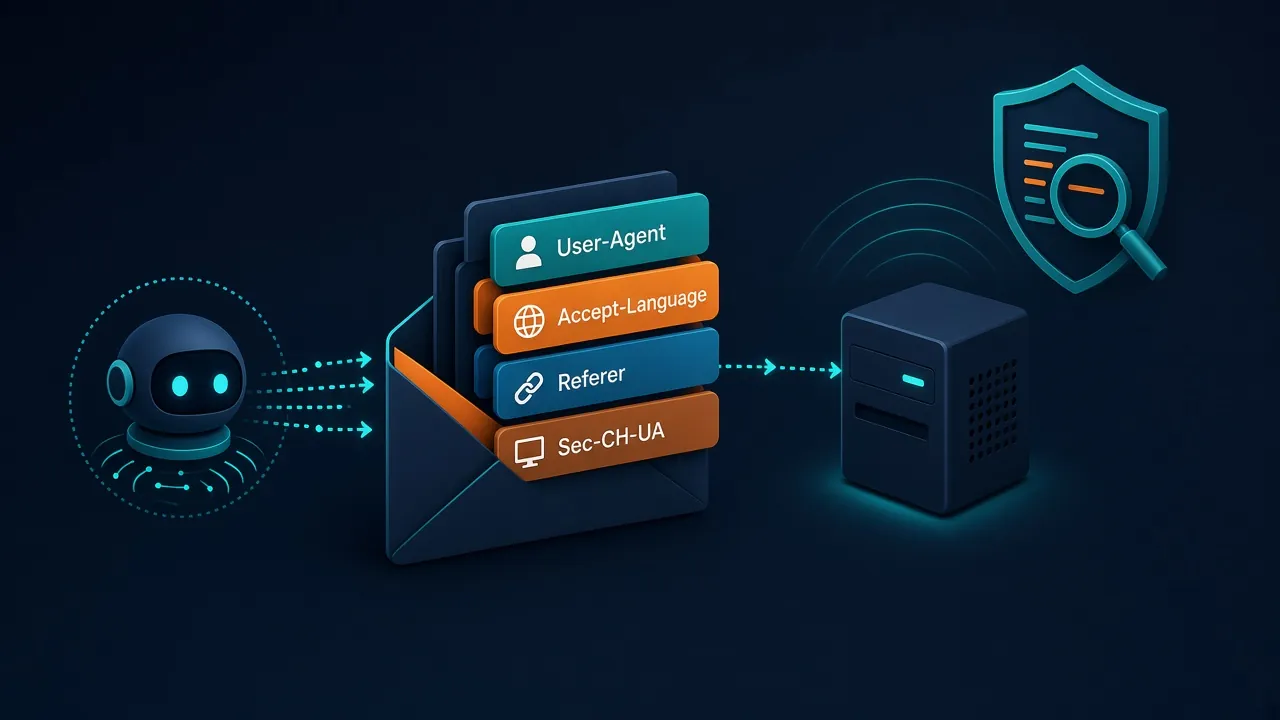
Learn which HTTP headers matter for web scraping, what a real Chrome request sends, why random user-agents backfire, and how header order gets fingerprinted, with Python examples.
Learn how to scrape JavaScript-rendered websites the smart way: find embedded JSON, call the hidden API, and use a headless browser only when you must, with code and cost trade-offs.
Route Python Requests through HTTP, HTTPS or SOCKS proxies the right way: authentication, sessions, environment variables, rotation, timeouts and the errors you’ll hit, with copy-paste code for each.
CAPTCHAs fire when a site’s bot score flags your traffic. Learn why they appear, how to detect them in code, how to reduce them with pacing, IP quality and consistent fingerprints, and when to switch to an API.
Robots.txt is not a lock, ToS is usually a civil risk, and proxies do not rewrite the law. A plain-English compliance map for scrapers in 2026.